SBPN: multilingual ASR models for Nigerian languages

  • Speech recognition models for Yoruba, Hausa, Igbo, Nigerian Pidgin and Nigerian English, which outperform other open-source models on these languages.
  • Two sizes, fine-tuned from NVIDIA Parakeet with NeMo: base (120M parameters) and large (600M parameters).
  • Described in the paper Sometin Beta Pass Notin, accepted at SLT 2026.

Speech Language Models

  • Research implementations of speech language models, focusing on recent advances in speech language modelling with acoustic codes.
  • Includes VQ-VAE, wav2vec, vq-wav2vec and wav2vec 2.0, following the original papers closely.

Iterative Vocoders for Phase Retrieval

  • Implements the iterative phase-retrieval vocoders from Beyond Griffin-Lim (Peer et al.).
  • Griffin-Lim, Fast Griffin-Lim, RAAR, Difference Map, ADMM, and hybrids that combine any of them.

ASR Statistical Significance Testing

  • Tests whether the word error rate difference between two ASR models is statistically significant, by computing a confidence interval with bootstrap sampling.
  • Supports blockwise bootstrap, e.g., sampling by speaker, gender or age.

SAINT: Neural Networks for Tabular Data

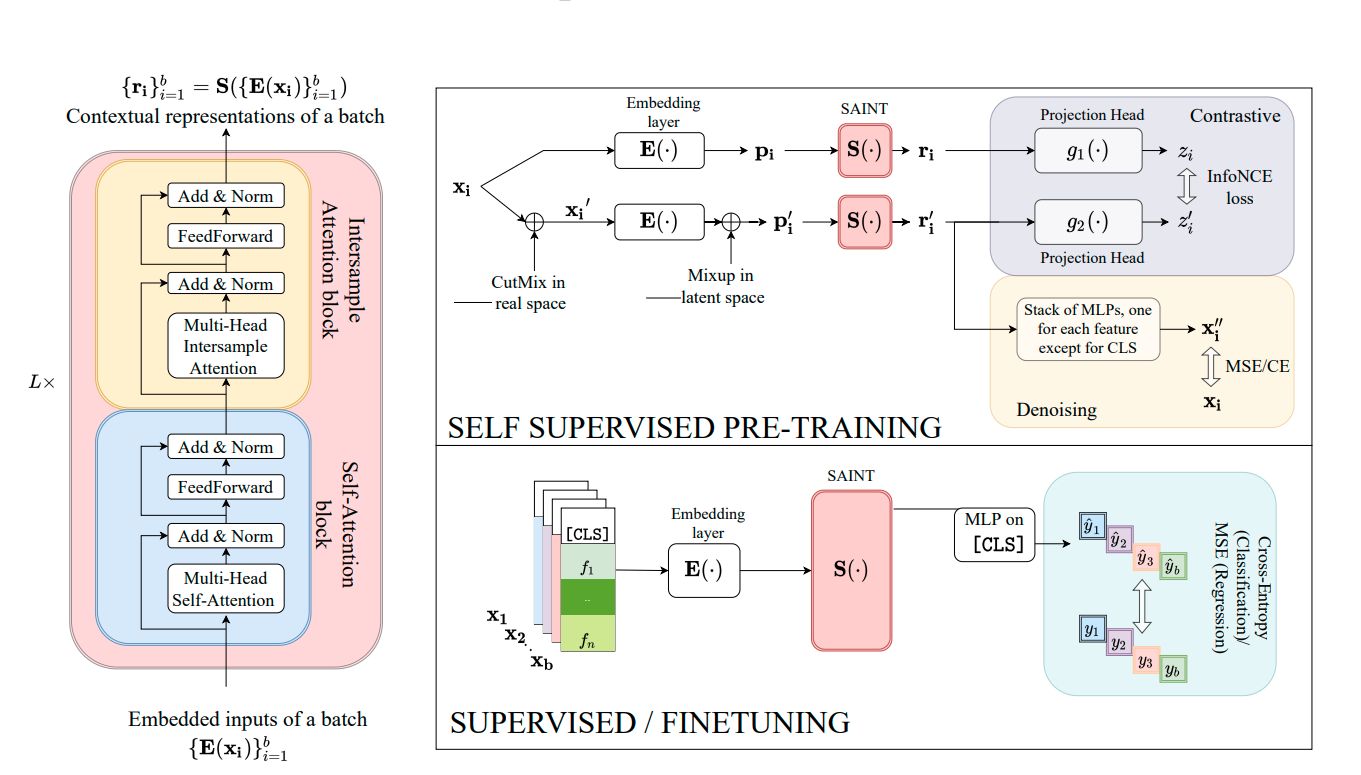
  • Unofficial PyTorch implementation of SAINT (row attention and contrastive pre-training), built in a week with a team of 8 research students.
  • Works with any tabular dataset for binary or multiclass classification, with PyTorch Lightning and Hydra configs.

Yoruba Speech Dataset: a dataset for low-resource speech tasks

  • 3 hours of audio recordings from a native Yoruba speaker.
  • Can be used for low-resource speech tasks.

Exploring Transfer of Self-supervised English Pretrained Model to Yoruba and French Languages in Very Low-Resource Settings

  • A self-supervised (CPC) model pretrained on a large amount of English speech is fine-tuned on 1 hour of labelled Yoruba and French audio.
  • We compare this to training from scratch on 1 hour of audio in the target language. Audio samples are from a single speaker.
  • Surprisingly, fine-tuning on a single speaker gave better results for Yoruba. Many factors could contribute, including speaker gender (male for Yoruba, female for French) and recording quality.
Exploring Detectron2 for Object Detection Tasks

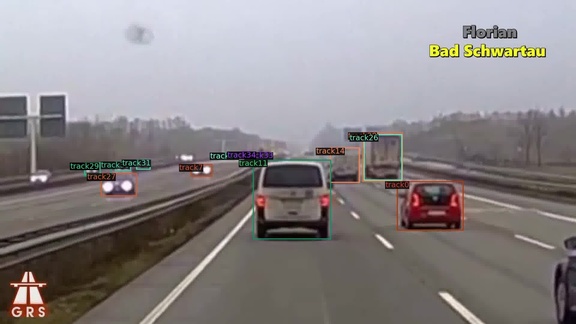
  • Instance segmentation, pose estimation and object tracking with the Detectron2 library.
  • Pretrained models fine-tuned on custom tasks.

Cassava Disease Classification

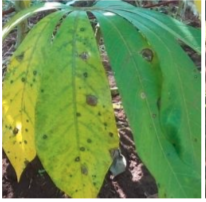
  • Classify cassava plants as healthy or as one of 4 disease classes.
  • Experimented with various CNN architectures.
  • Explored different ways of dealing with imbalanced datasets. I wrote a blog post on what worked for me.

DNA Sequence Classification using Kernel Methods

  • Predict whether a DNA sequence region is a binding site using kernel methods.
  • Experimented with mismatch, Gaussian and weighted-degree kernels.